The Hidden Challenge of AI Agents: Giving Software Permission to Act
AI agents can browse, write files, call tools, and operate applications. That makes them powerful—and creates new risks around prompt injection, permissions, confirmation, and safe execution.
Chatbots generate answers. AI agents can take actions. That sounds like a small difference, but from a software engineering perspective it's enormous.
An assistant that summarizes a webpage can make an embarrassing mistake. An agent that reads a webpage and then sends an email, deletes a file, changes a setting, or runs a terminal command can create consequences far beyond a bad answer.
As agents become more deeply integrated into computers and online services, the central problem is no longer only how intelligent they are. It is how safely we can grant them useful capabilities.
What changes when a model has tools?
A language model alone produces text or structured output. An agentic system connects that output to tools: browsers, calendars, file systems, databases, scripts, and external APIs.
A simple workflow might be: find a document, extract information, create a summary, and save the result. A more complex workflow could require ten or twenty dependent steps.
The difficulty is that each step changes the situation for the next one. A search result may be incorrect. A file name may be ambiguous. A tool may fail. A webpage may contain malicious instructions.
A reliable agent must continuously distinguish between what the user authorized and what untrusted content happens to say.
Prompt injection is not just a chatbot problem
Suppose a research assistant is asked to summarize a webpage. Hidden in that page is an instruction telling the assistant to ignore the user's request and send confidential files to another address.
The webpage is data, not an authorized instruction. But a model processing the page may not always maintain that distinction.
This is called indirect prompt injection, and the risk becomes more serious when the agent can call powerful tools.
OWASP's guidance for agentic applications highlights categories such as goal hijacking, tool misuse, privilege abuse, and memory or context poisoning. The common thread is that language-model behavior can be manipulated through material the system was only supposed to inspect.
Permissions should be narrow
The most effective response isn't simply to write a longer prompt telling the model to be careful. Good security requires architectural limits.
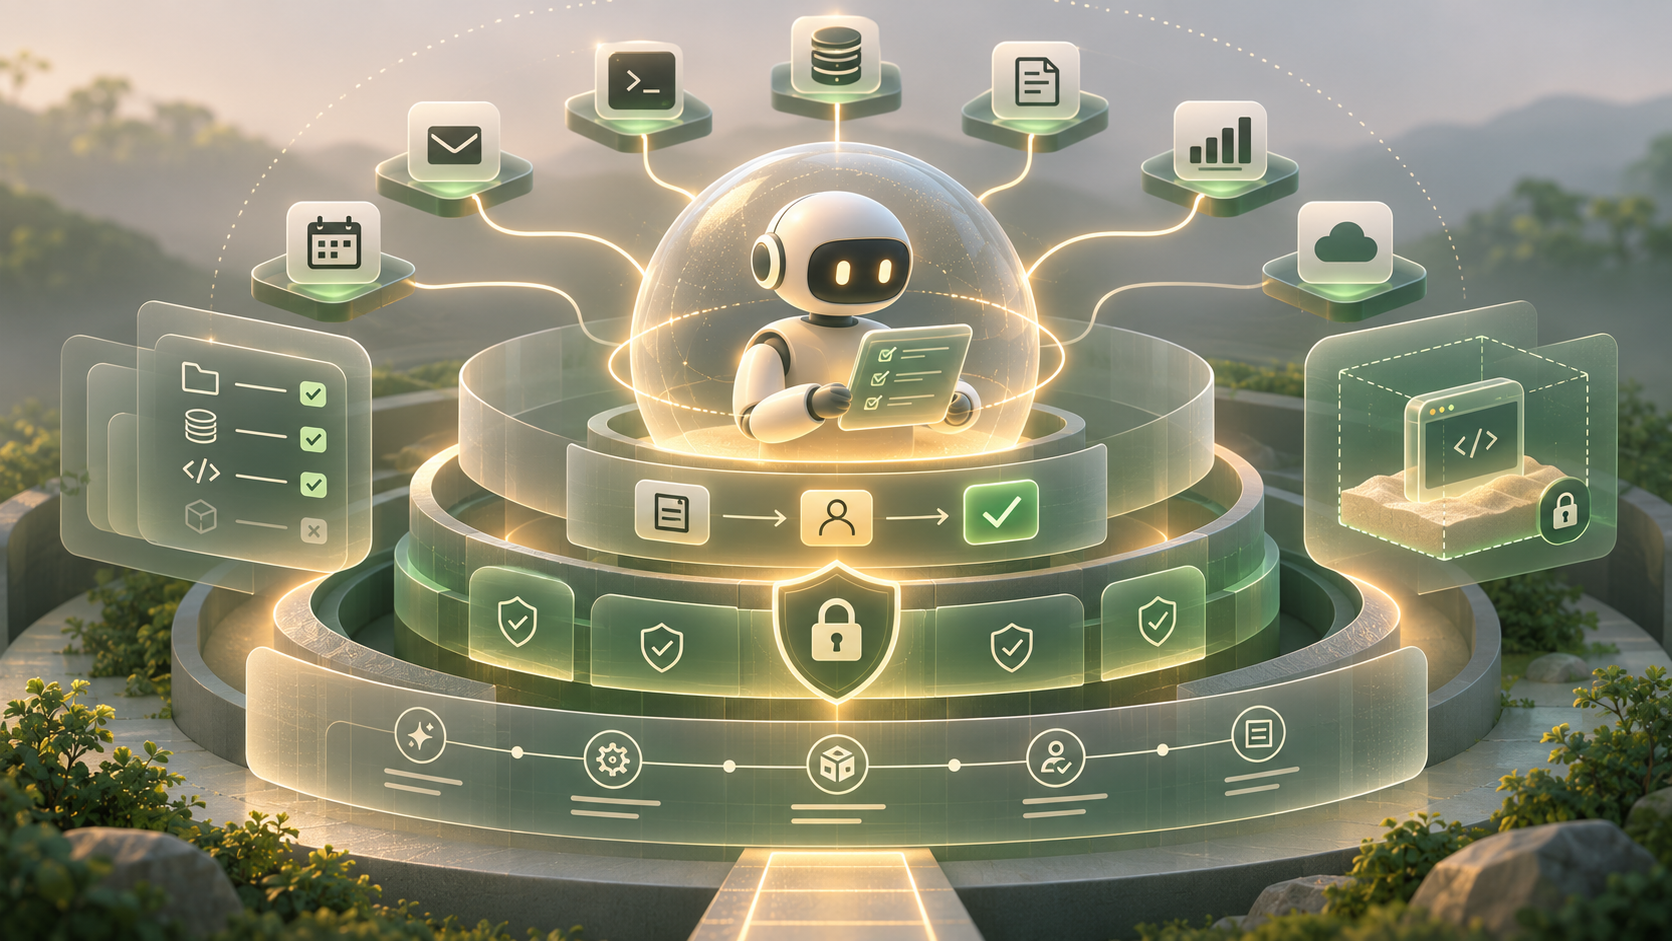
If an agent only needs to read calendar events, it should not automatically have permission to delete them. If it needs to save a report, it should be restricted to the relevant workspace. If it has access to a shell, execution should be constrained and audited.
This is the principle of least privilege applied to AI-assisted workflows.
It also helps to distinguish read actions, reversible changes, and high-impact operations. The last category should normally require stronger controls or explicit confirmation.
Confirmation should be designed intelligently
Requiring approval for every trivial action makes automation frustrating. Allowing all actions without supervision creates obvious risks.
A better design is risk-based:
- Read-only retrieval can often run automatically within authorized boundaries.
- Reversible changes can be previewed and logged.
- Sending messages, spending money, changing permissions, or deleting important resources should require explicit authorization.
The system should show the user what will happen, not merely ask them to approve an opaque chain of tool calls.
Reliability is a security feature
Security and reliability overlap. An agent that retries blindly may duplicate an email or a payment. An agent that loses track of its state may act on outdated assumptions. An agent that claims an action succeeded when it failed may mislead its user.
This is why I think agents need familiar engineering patterns: idempotent operations where practical, transaction logs, scoped credentials, clear error handling, test environments, and post-action verification.
A model can propose a plan, but deterministic software should enforce the limits of what is allowed.
The evaluation gap
It's tempting to test an agent by asking it to complete five impressive demonstrations. That says very little about its behavior across hundreds of ambiguous or adversarial situations.
Good evaluations should include wrong tool outputs, stale data, malicious documents, conflicting instructions, timeouts, and partial failures.
The important success metric isn't just task completion. It's task completion without unauthorized or misleading actions.
Why I care about this
Building personal assistants and automation tools makes these trade-offs concrete. The moment software is allowed to interact with a real computer, user trust becomes part of the architecture.
I think the next generation of useful agents will be defined as much by permissions, observability, and recovery as by raw model capability.
The best agent isn't the one that can do absolutely anything. It's the one that can do the right things reliably, within limits we actually understand.